GeoComposer: Geometry-Grounded
Photographic Composition Instruction

Shuangzhi Li1,2,*,† Qiaoqiao Jia1,3,*,† Xingxin Chen1 Guile Wu1 Dongfeng Bai1
1Huawei Noah's Ark Lab    2University of Alberta    3University of Waterloo
*This work was done during internships at Huawei Canada.    †Equal contribution.
GeoComposer Teaser

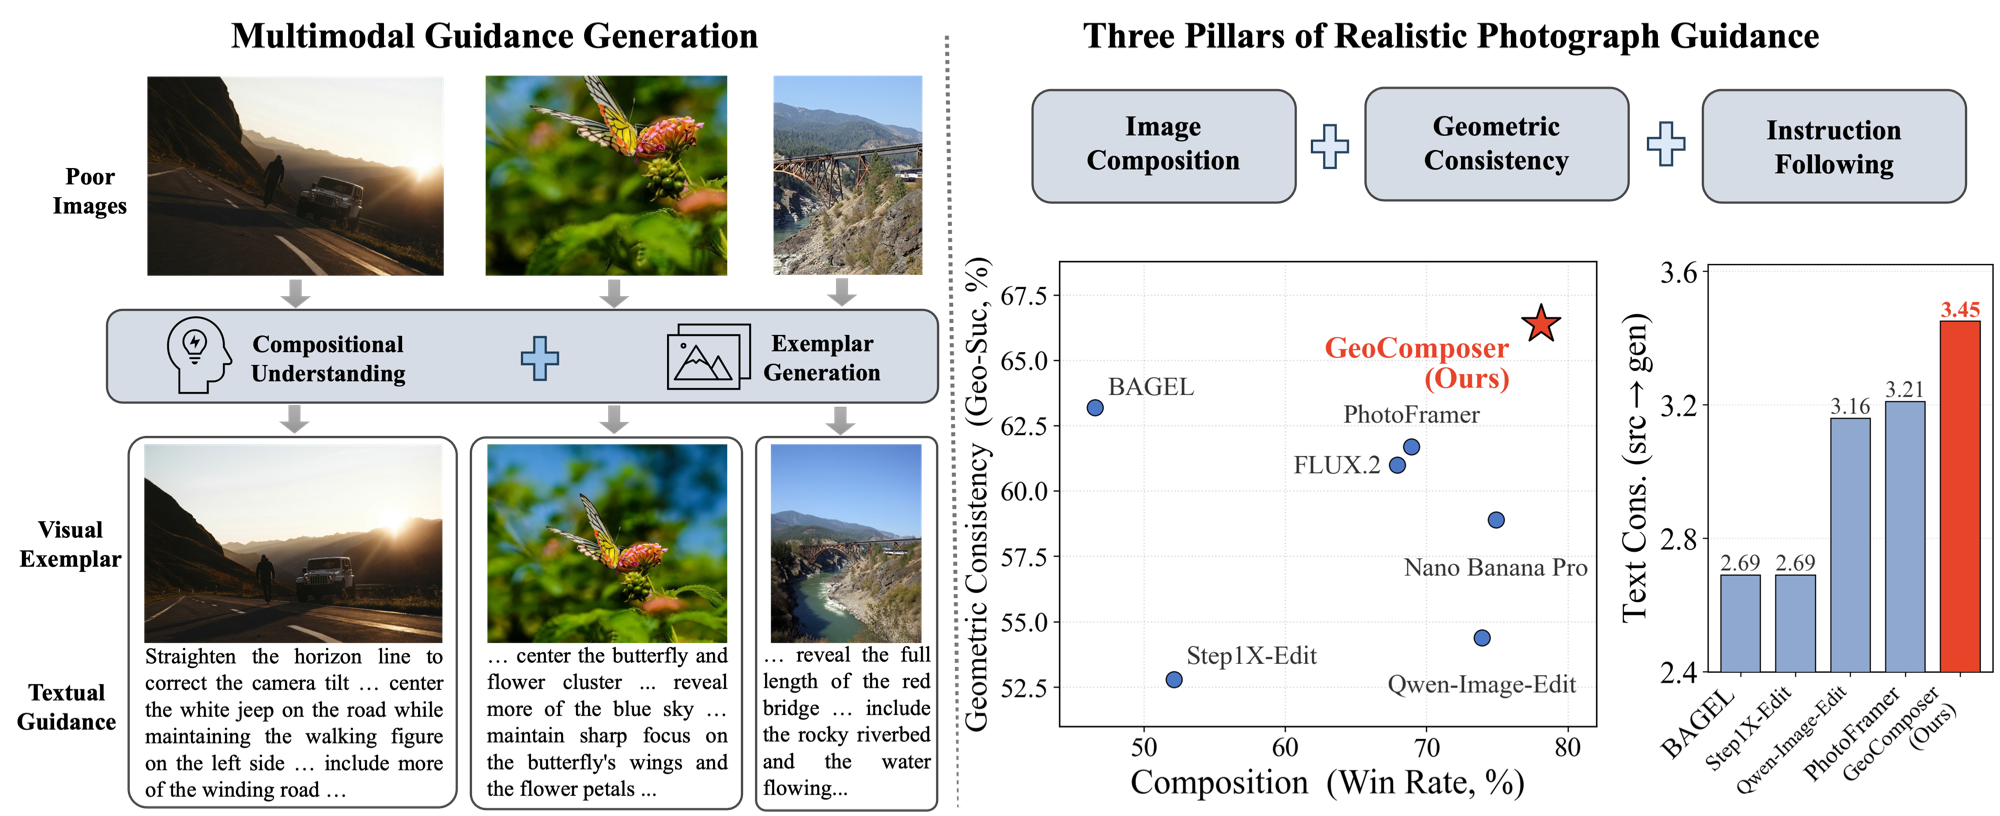
Figure 1. Given a poorly composed photograph, GeoComposer generates textual guidance together with a geometry-consistent visual exemplar as the composition improvement guidance, achieving the best balance between composition quality and geometric consistency among existing methods.
Abstract

Photographic composition aims to provide visual guidance for improving the framing, viewpoint, and spatial arrangement of an image. Early methods primarily rely on image cropping to enhance composition, which is restricted to the viewpoint and spatial arrangement of the input image. Recent methods have explored image understanding and editing to improve composition, but they mainly focus on instruction following and aesthetic quality, overlooking the importance of 3D scene geometry consistency for photographic composition. In this work, we propose GeoComposer, a novel geometry-grounded photographic composition framework that analyzes the composition of a given image to generate textual guidance and synthesizes a visual exemplar that enhances the composition of the given image. To promote geometry-grounded composition, we propose a geometry-aware representation learning mechanism that leverages geometric priors from a visual geometry foundation model to shape the intermediate representations of the composition editing model. This mechanism preserves both global structural relationships and local fine-grained correspondences for geometry-grounded composition. Furthermore, we propose a reinforcement learning strategy guided by a hybrid reward that jointly optimizes instruction following, aesthetic quality, and geometric consistency. This enables the model to generate visual exemplars that faithfully follow the composition instructions while remaining visually appealing and geometrically consistent. Extensive experiments show the superiority of our approach over state-of-the-art methods, highlighting its effectiveness in generating visually appealing and geometrically consistent composition.

Method

GeoComposer Framework

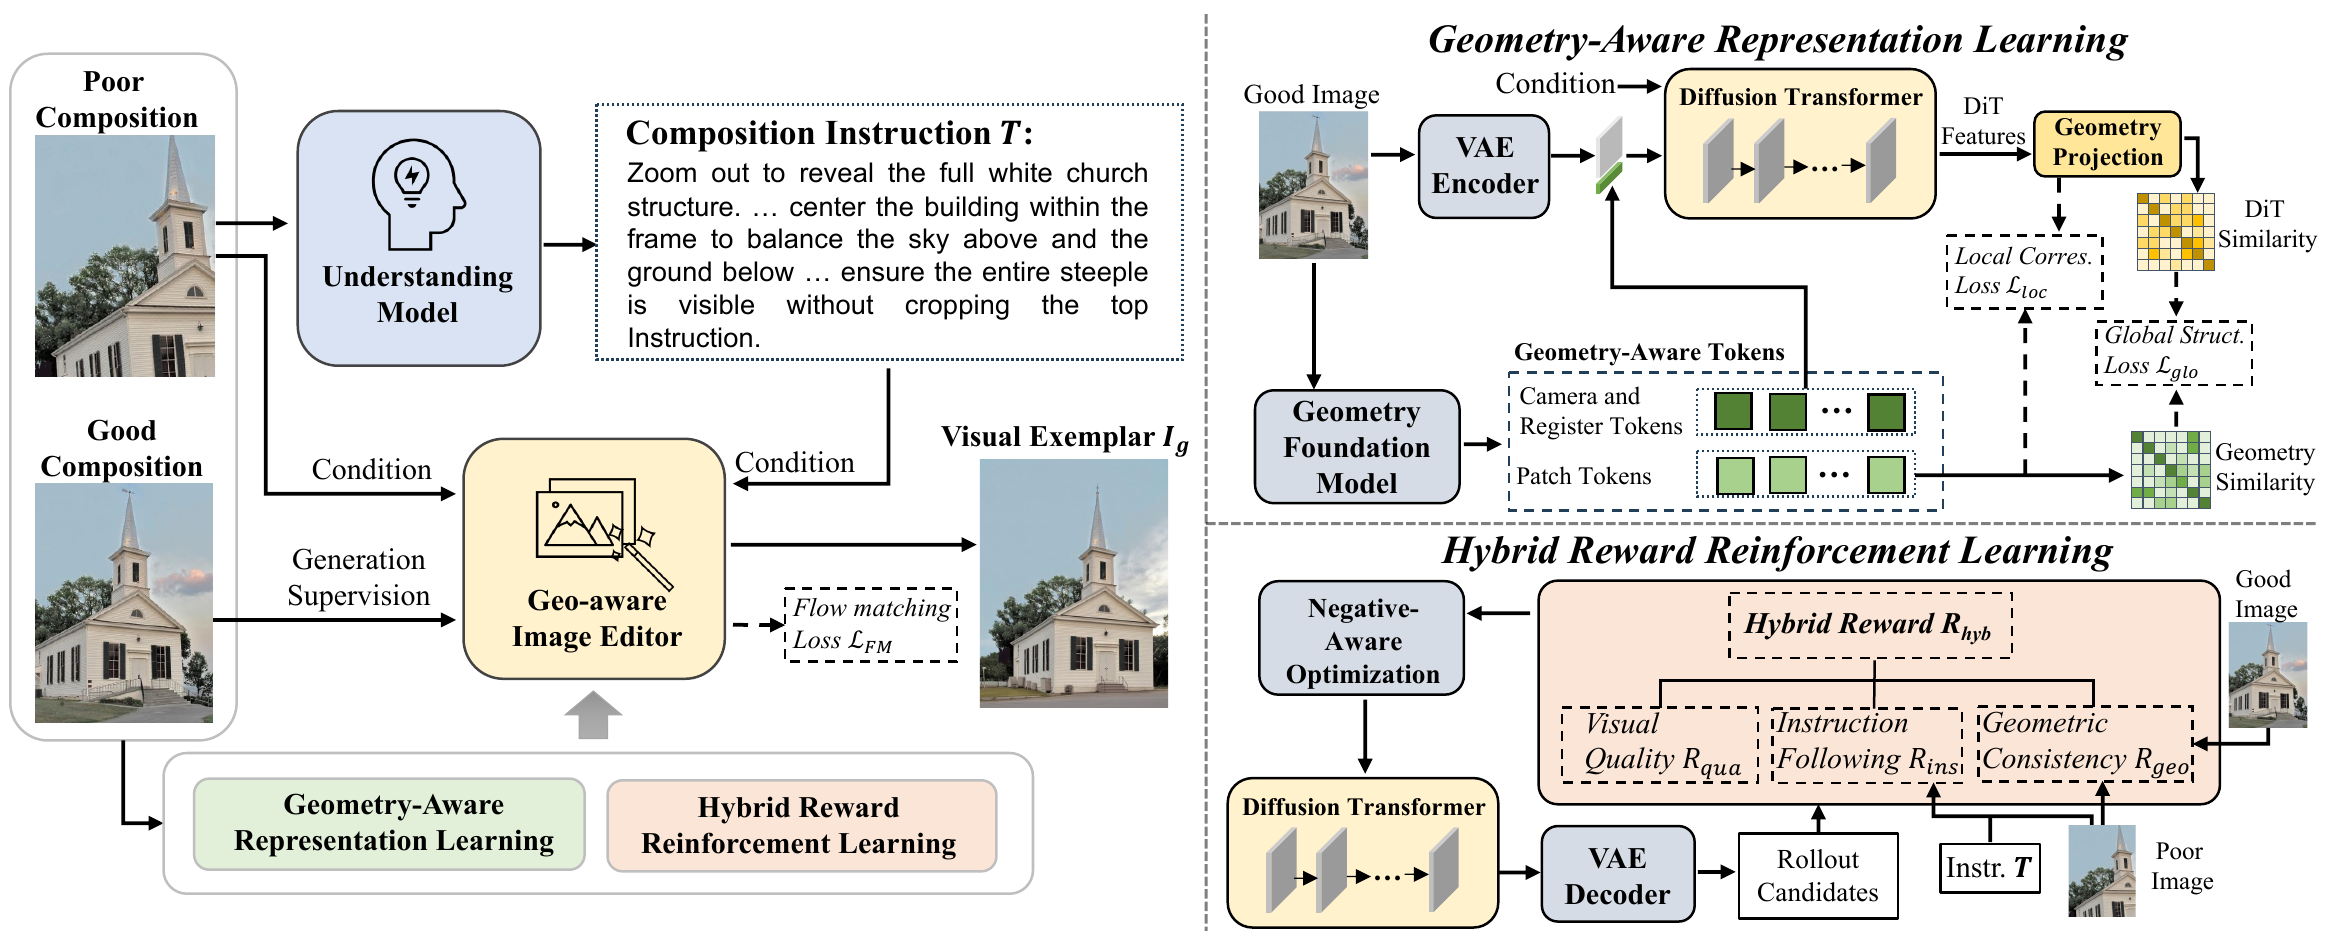
Figure 2. The overall framework of GeoComposer. A composition understanding model analyzes the poorly composed input and produces textual guidance, which conditions a geometry-aware image editor to synthesize a well-composed visual exemplar. Stage I distills geometric priors from a visual geometry foundation model into the editor via geometry-aware representation learning; Stage II further optimizes the editor with hybrid reward-guided reinforcement learning.

Contributions

Results

78.1%
Composition Win Rate
(best among all methods)
66.4%
Geometry Success
(best among all methods)
0.184
MET3R ↓
(best geometric consistency)
85.6%
Human Study Overall
(vs. 63.9% runner-up)
Method Composition Image Quality Geo. Consistency Text Guidance Human
WinRate (%) ↑PF-ass ↑ QAlign ↑DeQA ↑ Geo-Suc (%) ↑MET3R ↓ src→gen ↑src→GT ↑ Overall ↑
BAGEL46.52.5882.8233.59863.20.2462.692.5743.3
Step1X-Edit52.12.7042.8703.49652.80.2312.692.30--
Qwen-Image-Edit73.92.9873.2723.86954.40.2573.162.6059.4
FLUX.267.92.9483.1333.82061.00.233----40.6
PhotoFramer68.92.9573.0433.81261.70.2313.212.6963.3
Nano Banana Pro74.93.0813.3234.04158.90.191----63.9
GeoComposer (Ours)78.13.1333.3814.01266.40.1843.453.2885.6

Table 1. Quantitative comparison with state-of-the-art methods on the constructed validation set. Blue bold and underline mark the best and second-best results; "--" denotes unavailable results.

Qualitative Results

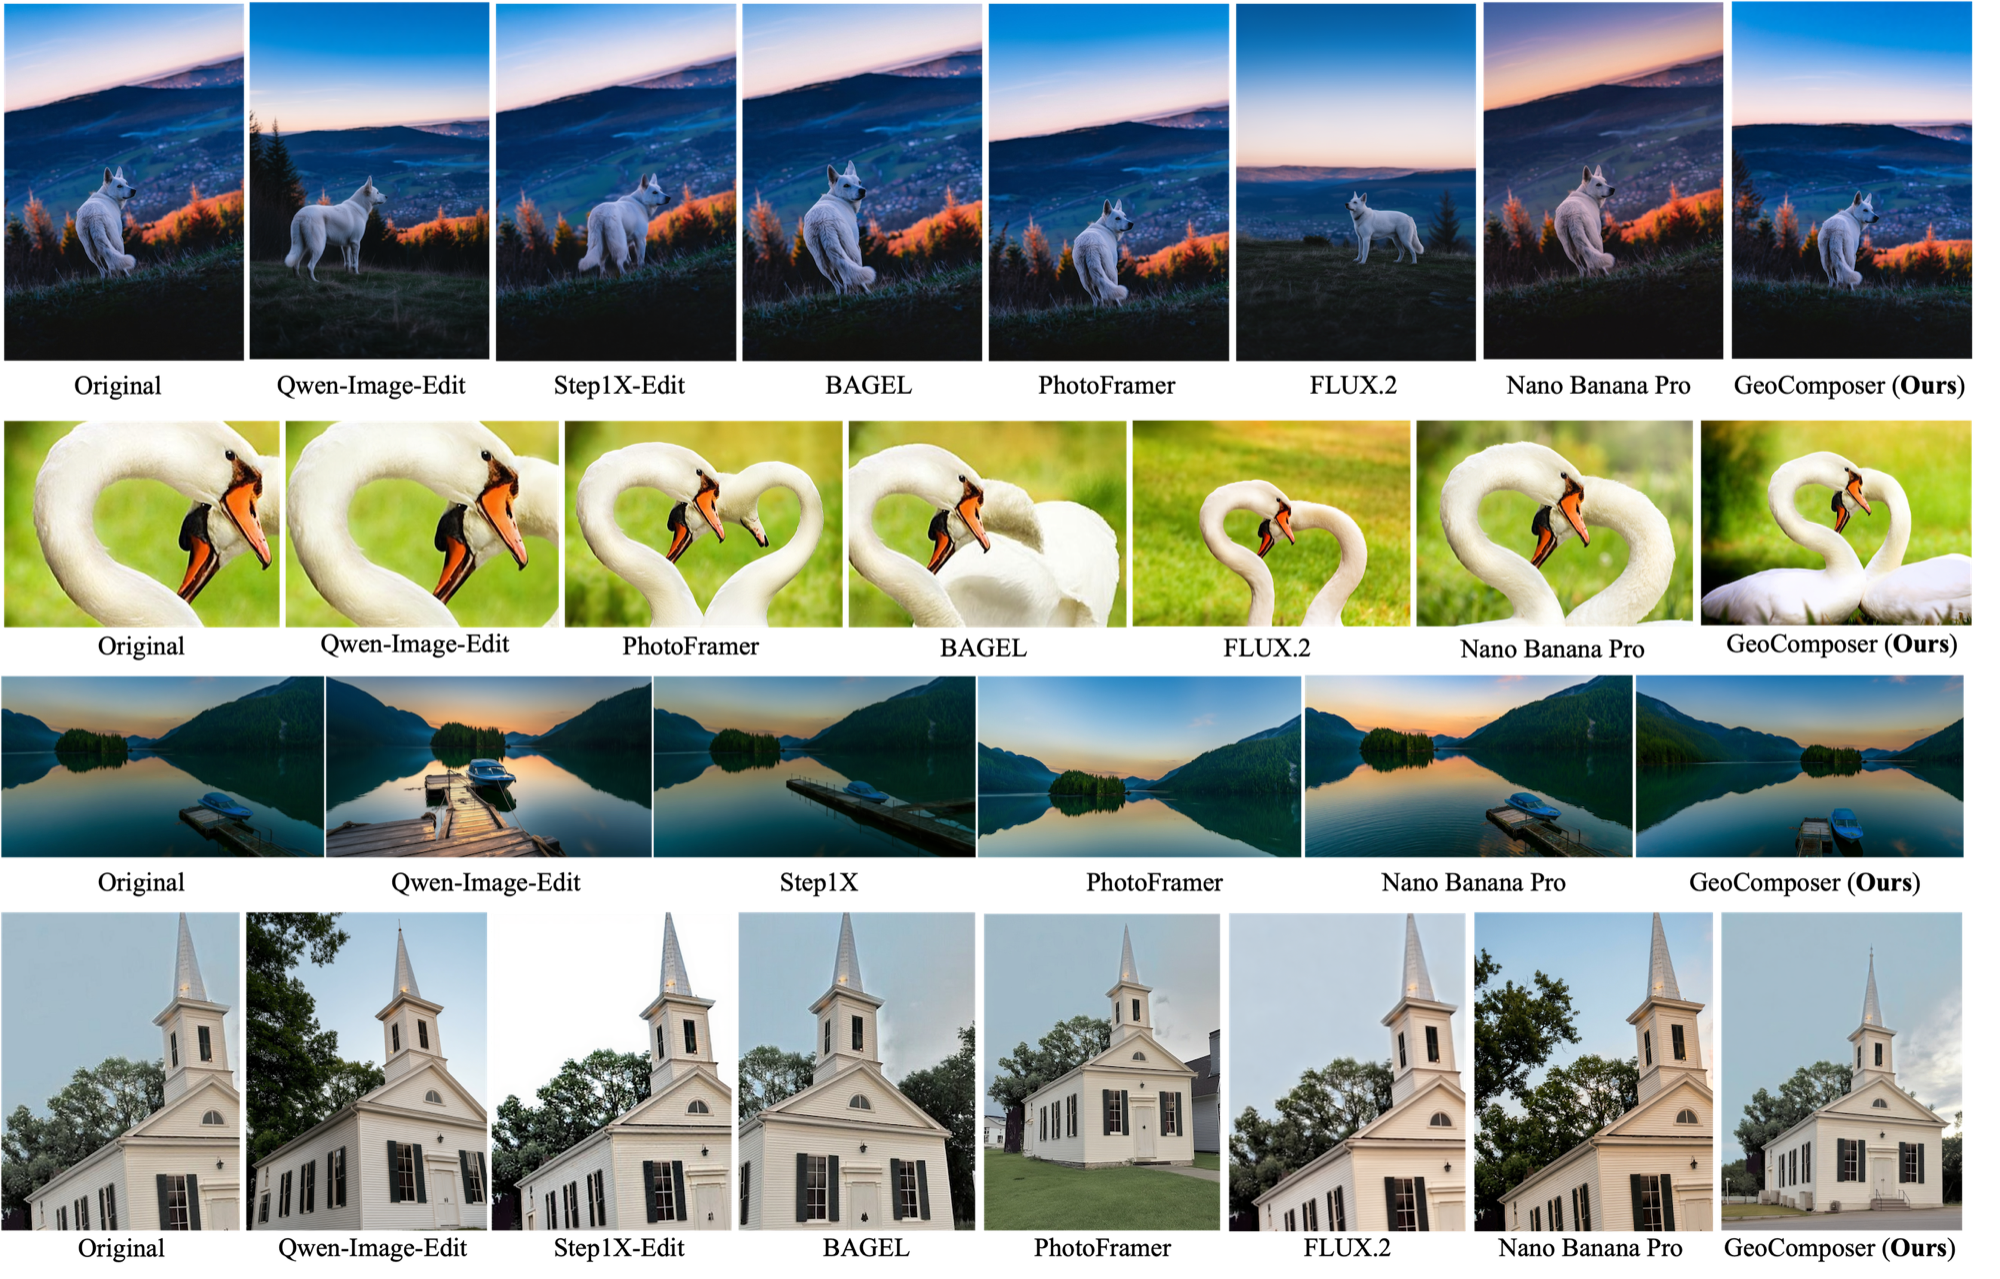
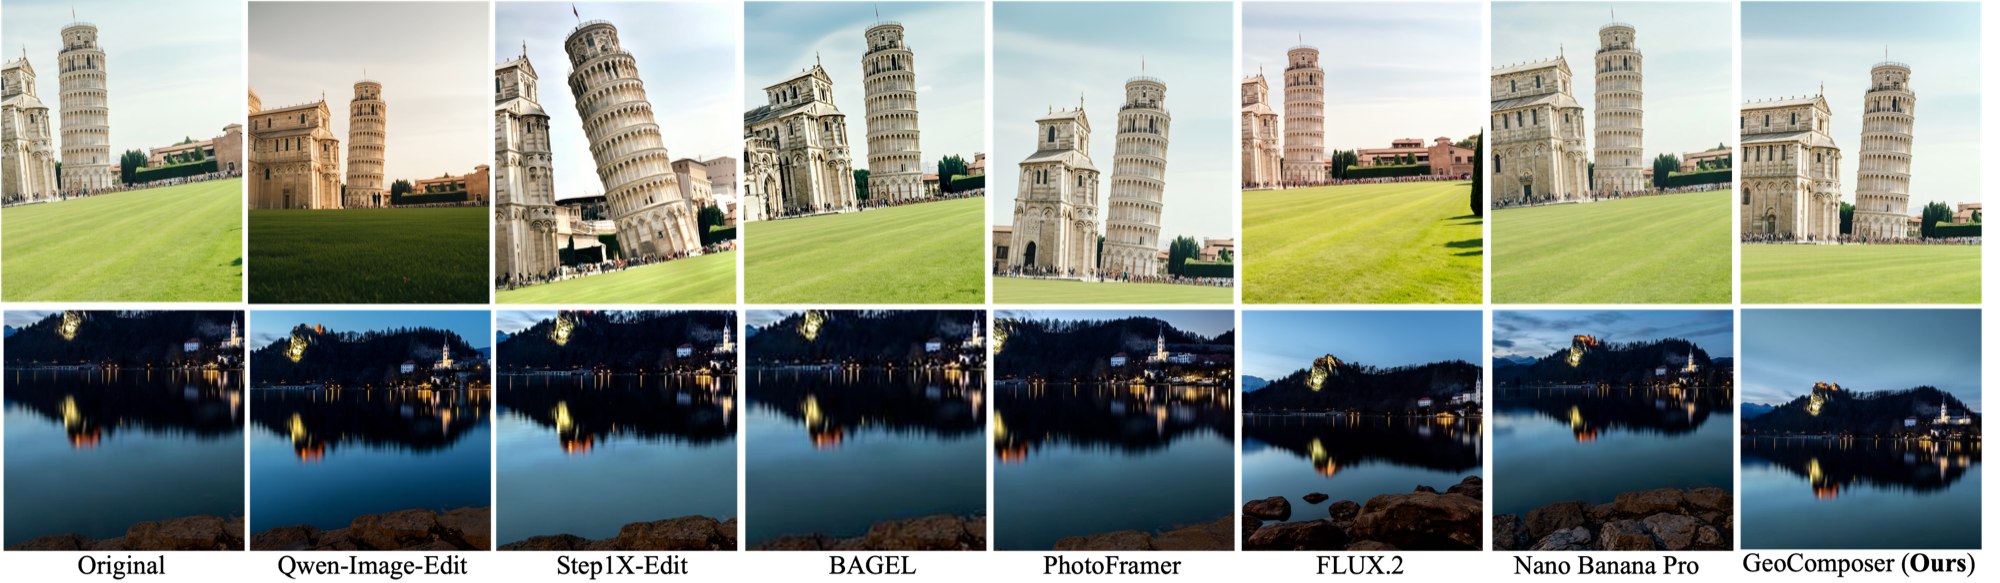
Figure 3. Qualitative comparison with state-of-the-art methods.

Additional Qualitative Results

Figure 4. Additional qualitative comparison on diverse scenes. In each row, the leftmost image is the poorly-composed input and the rightmost is the result of GeoComposer.

Word Distribution of Textual Guidance

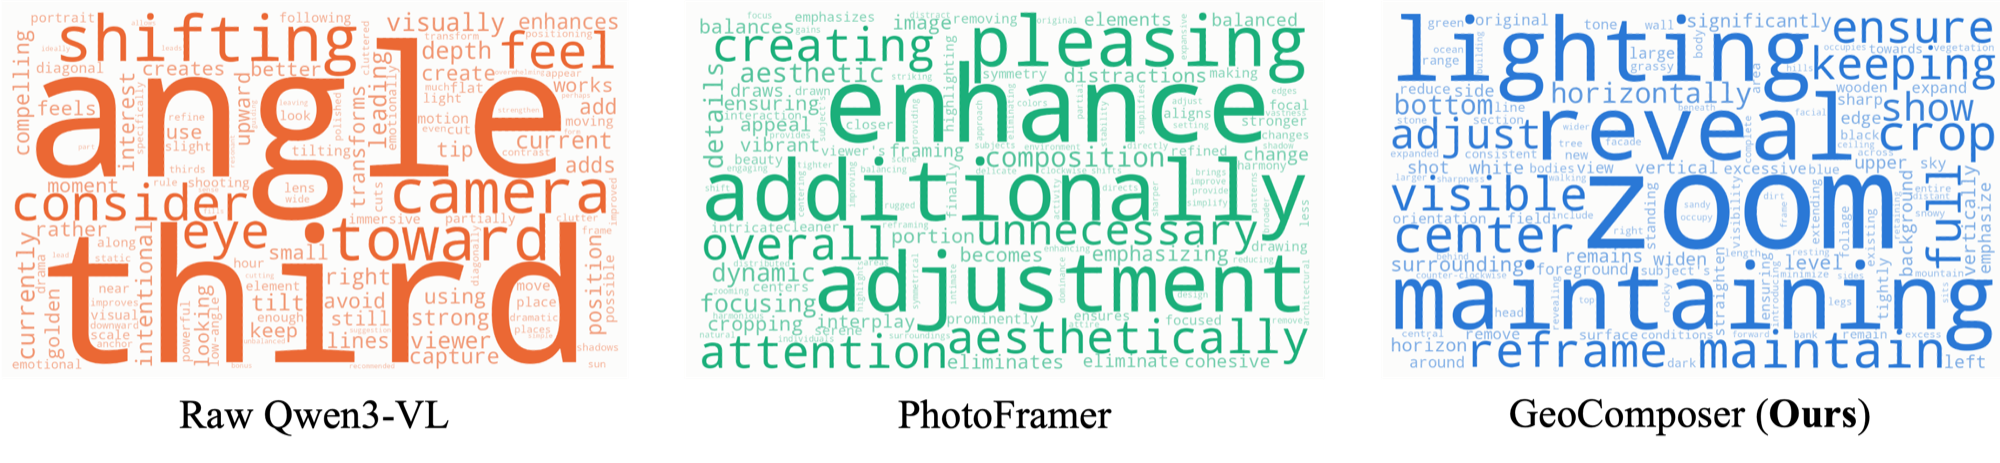
Figure 5. Word distribution of the textual guidance produced by each composition understanding model over the validation set.

BibTeX

If you find this work useful, please cite our paper:

@article{li2026geocomposer, title = {GeoComposer: Geometry-Grounded Photographic Composition Instruction}, author = {Li, Shuangzhi and Jia, Qiaoqiao and Chen, Xingxin and Wu, Guile and Bai, Dongfeng}, journal = {arXiv preprint arXiv:2609.26620}, year = {2026}, }